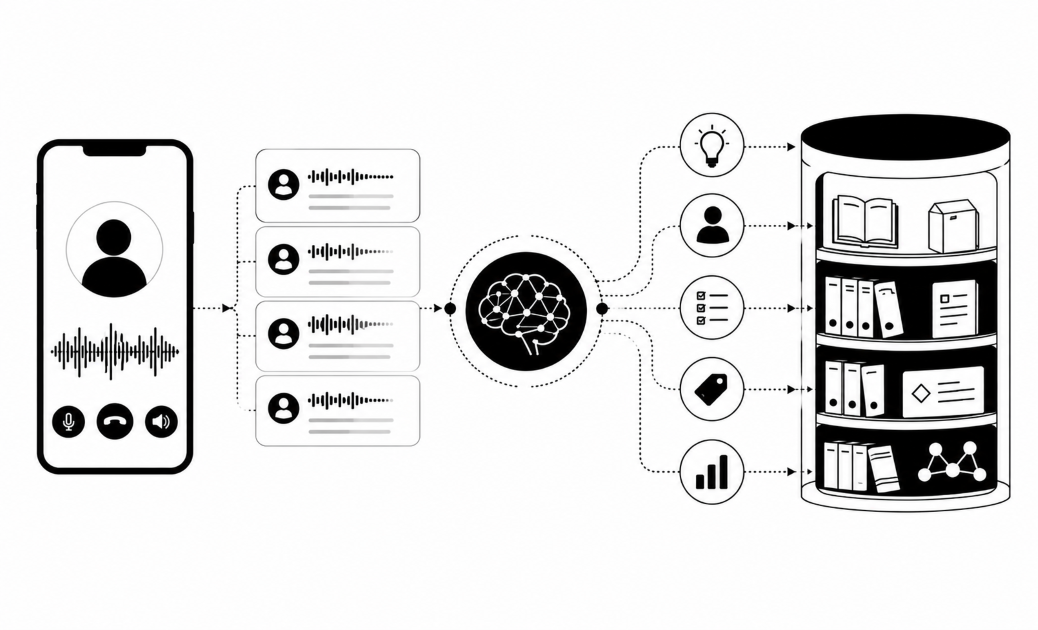

An automated outage alert call is a call a system places when monitoring raises a site-down alarm, so no operator has to dial. To automate network outage alert calls, keep your monitoring and ticketing tools. Automate only the dial, escalate, ticket and update loop between them.
Pick which alerts deserve a phone call
Start with site-down alerts only. A phone call is the loudest tool you have, so spend it on the alarm where every minute costs money. A narrow first scope is also easier to test and trust. A telecom infrastructure manager we spoke with limited the first rollout to site-down alert calls.
Next, get the alarm out of your monitoring tool. Most tools can push an event over HTTP. Zabbix, for example, has a webhook media type for making HTTP calls with custom JavaScript, aimed at helpdesk systems, chats and messengers (Zabbix webhook documentation). Older tools send an SNMP trap or an email. Route those into an incident tool that can forward a webhook to the calling system.
Then filter before anything dials:
- Dedupe: one site and one alarm ID should give one call, however many times the tool repeats the alert.
- Flap suppression: hold a "down" state for a few minutes before it counts. A link that bounces should not wake an engineer.
- Severity: critical alarms get a voice call. Major ones go to chat or SMS. Minor ones go straight to the ticket queue.
- Maintenance windows: mute sites under planned work, so engineers are not called about their own change.
Test the filter on last month's alarms before you switch it on. Count how many would have rung a phone. If one engineer would have been called often, tighten the rules first.
Write the escalation matrix before the automation
Write the escalation matrix first, because automation can only follow an order that already exists. A NOC escalation matrix is a table that says who gets called for each site, in what order, and how long to wait at each level. The manual version is simple: call the person who manages the site, and if they do not pick up, go to the next level.
Build the table with one row per site or site group:
| Level | Who | Wait before next level | Tries |
|---|---|---|---|
| 1 | Engineer who owns the site | 5 minutes | 2 |
| 2 | Level 2 engineer on the rota | 5 minutes | 2 |
| 3 | Regional lead | 10 minutes | 1 |
| 4 | NOC manager | Stop and hand to a human | 1 |
These timers are a starting point for critical alarms. Tune them to how fast your field teams can reach a site. Many alerting tools default to long timeouts built for slow incidents, so shorten them for site-down alarms. Stop escalating the moment someone acknowledges, and cap the number of repeats so a loop cannot run forever.
Keep contacts in one place. Your rota tool or ITSM schedule should be the source of truth, and the calling system should read from it. Add a backup number for every level.
Define "acknowledged" strictly. A voicemail pickup is not an acknowledgment. Neither is a call where only the automated voice spoke. A silent line, a voicemail or a "no" should all send the alarm to the next level. Put that rule in your matrix.
Let the call ask for a spoken acknowledgment
Make the call short and give it one question to answer. The script should state the site, the alarm and the start time, then ask: "Can you take this? Say yes or no." A clear yes or no is easy to capture. A long conversation is not.
A good script has four parts:
- Site and alarm: "Site Lagos North is down. Power alarm."
- Start time: "It started at 02:14."
- The question: "Can you take this now? Say yes or no."
- Close: On yes, say a ticket is coming. On no, say the next person will be called.
Set the rules around the call as carefully as the words. Set calling hours to 24 hours for this campaign, so critical alarms are never blocked. Use the retry counts from your matrix, and wait a few minutes between tries.
Record one outcome per call: acknowledged, declined or no answer. That result should come from the transcript, because it is the proof of who said what.
Say that the caller is an AI. Article 50 of the EU AI Act has applied since 2 August 2026 and requires AI that talks to people to say so from the first interaction. In the US, AI-voice calls already need consent under the FCC's 2024 TCPA ruling.
Insight7 runs outbound AI calling campaigns, now in beta. Managers set the goal, the audience, the AI caller and the rules. The agent can be tried in the browser with no phone number. A dashboard shows calls in progress, and each transcript can be read when the call ends. Calls where only the AI spoke are not counted as reached, and a carrier's temporary refusal does not use up a retry attempt. Ask for a demo to confirm how your alert source would trigger a call and how a next level would be dialed.
Open and link the ticket on acknowledgment
Open the ticket when the alarm fires, and update it when the call ends. Your ITSM tool stays the record. The calling system only writes to it. Buyers ask first whether a new tool replaces their stack or plugs into it, and this design plugs in.
Give every alarm one stable ID, and attach it to the ticket. Before creating anything, look up that ID. If a ticket exists, update it. This stops a repeated alert from making a second ticket. Most ITSM tools offer an external reference field for this. Check your tool's API docs for the name.
Fill these fields from the call outcome:
- Site and alarm: copied from the alert.
- Start time: the alarm time, not the ticket time.
- Owner: the person who said yes.
- Escalation level reached: 1, 2, 3 or 4.
- Call outcome: acknowledged, declined or no answer.
- Transcript link: so anyone can hear what was said.
Link the ticket ID back to the monitoring incident, so the alarm screen shows it.
Refresh the status board until the site clears
Post a status board every 15 minutes, and show each down site with its running outage duration. As an illustration, take a site that went down at 09:00. The 09:15 board lists it with 15 minutes of outage, and a 09:30 board would list it with 30 minutes. The start time never changes, only the duration grows.
The field engineer fixes the site and closes the ticket with root cause notes. That close event clears the site from the tracker, so the next board leaves it off. If the site is not restored, it stays on every board with a longer duration. Build the board as a query on open tickets, so nobody removes a row by hand.
Stakeholders need words as well as a board. Use a fixed template with three parts: what happened, what the impact is, and when the next update comes. Always give a time for the next update. While customers are affected, never go more than an hour without one. A 15-minute internal board suits a NOC watching hundreds of sites.
Review five numbers each week:
- Time to acknowledge: alarm start to the first spoken yes.
- Time to escalate: how long a no answer waited before the next level rang.
- Unanswered calls: which levels or contacts miss calls most often.
- Duplicate tickets: should be zero if the alarm ID rule works.
- Mean time to restore: alarm start to ticket close.
Then read a few transcripts from the slowest outages. They show whether the script, the contact list or the timers caused the delay.
Related reading: How to Add an AI Voice Agent to Your Existing IVR Without Replacing Your Phone System, 12 Post-Call Automation Workflows That Create Tickets, Send SMS and Update Your CRM and How to Use AI Voice Agents for First Contact and Pass Interested Customers to Sales Reps.
Questions people also ask
What is a NOC escalation matrix?
It is a table that maps each site or alarm type to the people who handle it, level by level. Some matrices escalate up the management chain. Others escalate across skills, such as power, transmission or core network.
What is the NOC escalation process?
It is the path an alarm follows until someone owns it. The NOC calls the site owner and moves to the next level on no answer. A ticket tracks the fix. The engineer closes it with root cause notes.
What should a network outage notification include?
Include the affected site or service, the start time, who is hit, the current status, the next update time and the ticket reference. Skip guesses about the cause until you know it.
How long should a NOC wait before escalating to the next level?
Match the wait to the outage cost and how fast you can act. Five minutes per level is a sensible start for critical site-down alarms. Check your weekly time-to-escalate numbers, then tighten or relax the timers.
Can AI make outage alert calls without replacing our monitoring and ticketing tools?
It can if the design is right. The AI caller should sit between the tools: take the alert in, make the call and write the outcome to the ticket. Insight7 runs outbound AI calling campaigns in beta. Confirm the alert trigger and ticket link in a demo.
What should happen when nobody answers the outage call?
Retry as the matrix says, then call the next level. After the last level, route the alarm to a person on the NOC floor and mark it unacknowledged on the board. An alarm should never run out of steps silently.
How often should you send a network status notification during an outage?
Run the internal board every 15 minutes. For customers, send an update at least hourly. Always state when the next one is due.
Automate the loop, not the NOC
Automate the narrow loop between alert, call, ticket and status, and leave the rest of the NOC alone. This week, list last month's site-down alarms. Then write the escalation order and timers for the top one.