
TL;DR
A contest process is not the button that lets an agent object to a score. It is the workflow that decides who is allowed to raise the challenge, what happens to the disputed call, and whether the rule that produced the score gets fixed so the same complaint does not come back next month. Ship the button first and you get a queue of individual disputes with no way to tell whether the underlying rubric is sound. Get the decisions behind the button right, and you will spend far less time relitigating single calls and far more time fixing the handful of criteria that keep generating complaints.
Four Decisions Before You Build
Work through these four decisions before you turn on any contest flow, whether the scoring behind it is manual or AI assisted. Skip one and the workflow you ship will produce more disputes than it resolves.
| Decision | What to settle before launch |
|---|---|
| Who can initiate a contest | Match it to whoever already owns the scorecard in your manual process, not to agent self-service by default. |
| What happens once a contest is raised | Decide whether it triggers a manual re-listen of that specific call, who does the re-listen, and on what turnaround. |
| Whether any criterion can zero out the whole score | Find every all-or-nothing trigger in the rubric and stress-test it against real calls before it goes live. |
| Whether a contest is a one-off or a pattern | Track disputes by the rubric item they hit, not only by agent, so a repeat contest gets treated as a design flaw rather than another ticket. |
The first and third rows are the ones teams usually only get right on the second try, after a customer has already told them the button did not match their operation. The next few sections work through why.
Match Contests To Your Ownership Structure
Build the contest trigger around whoever already owns the scorecard in your manual process. Do not default to agent self-service just because that is the easiest thing to switch on.
An insurance company running a contact center of over a hundred staff, handling policy and claims calls, was midway through a customer check-in session when the head of contact center pushed back on an agent-facing request-review button that had just been shown. She had just been shown an agent-facing request-review button and pushed back immediately: in her operation, a contest has to be raised by the supervisor on behalf of the agent, never self-served by the agent directly. Their manual QA process runs on a grading sheet that a dedicated evaluation team owns, and scorecards are expected to reach the supervisor first, then cascade to the agent on a set weekly cadence. A contest button that lets the agent challenge their own number the moment they see it skips past that ownership structure entirely, and in a regulated industry, the supervisor is the one accountable for what gets recorded as the official evaluation.
If supervisors currently review and release scorecards before agents see them, route the contest through the supervisor too. Do not let a self-serve button skip past who is accountable for the official record.
High Scores Can Still Be Wrong
Expect an agent to use a technically high score to contest a manager's judgment whenever the rubric rewards the presence of a question rather than the depth of the answer.
A telehealth provider running remote clinical assessments audits its assessors by watching the videoed calls back and scoring them personally. Its clinical lead had already decided to part ways with one assessor over clinical quality when the automated score for that same assessment came back at 84%. That is high enough, he said, for her to point to it and contest his verdict that she was not good enough for the service. The criteria rewarded a warm, professional manner and the presence of the right questions, but missed follow-up depth. The checklist item was satisfied. The judgment underneath it was not.
A score built to catch missing questions will always be contestable by someone who asked every question on the list and still did the job poorly.
Kill The Zero-Score Trigger First
Find every criterion in your rubric that can zero out an entire score on its own, and check whether its trigger fires even when the information came through elsewhere on the call.
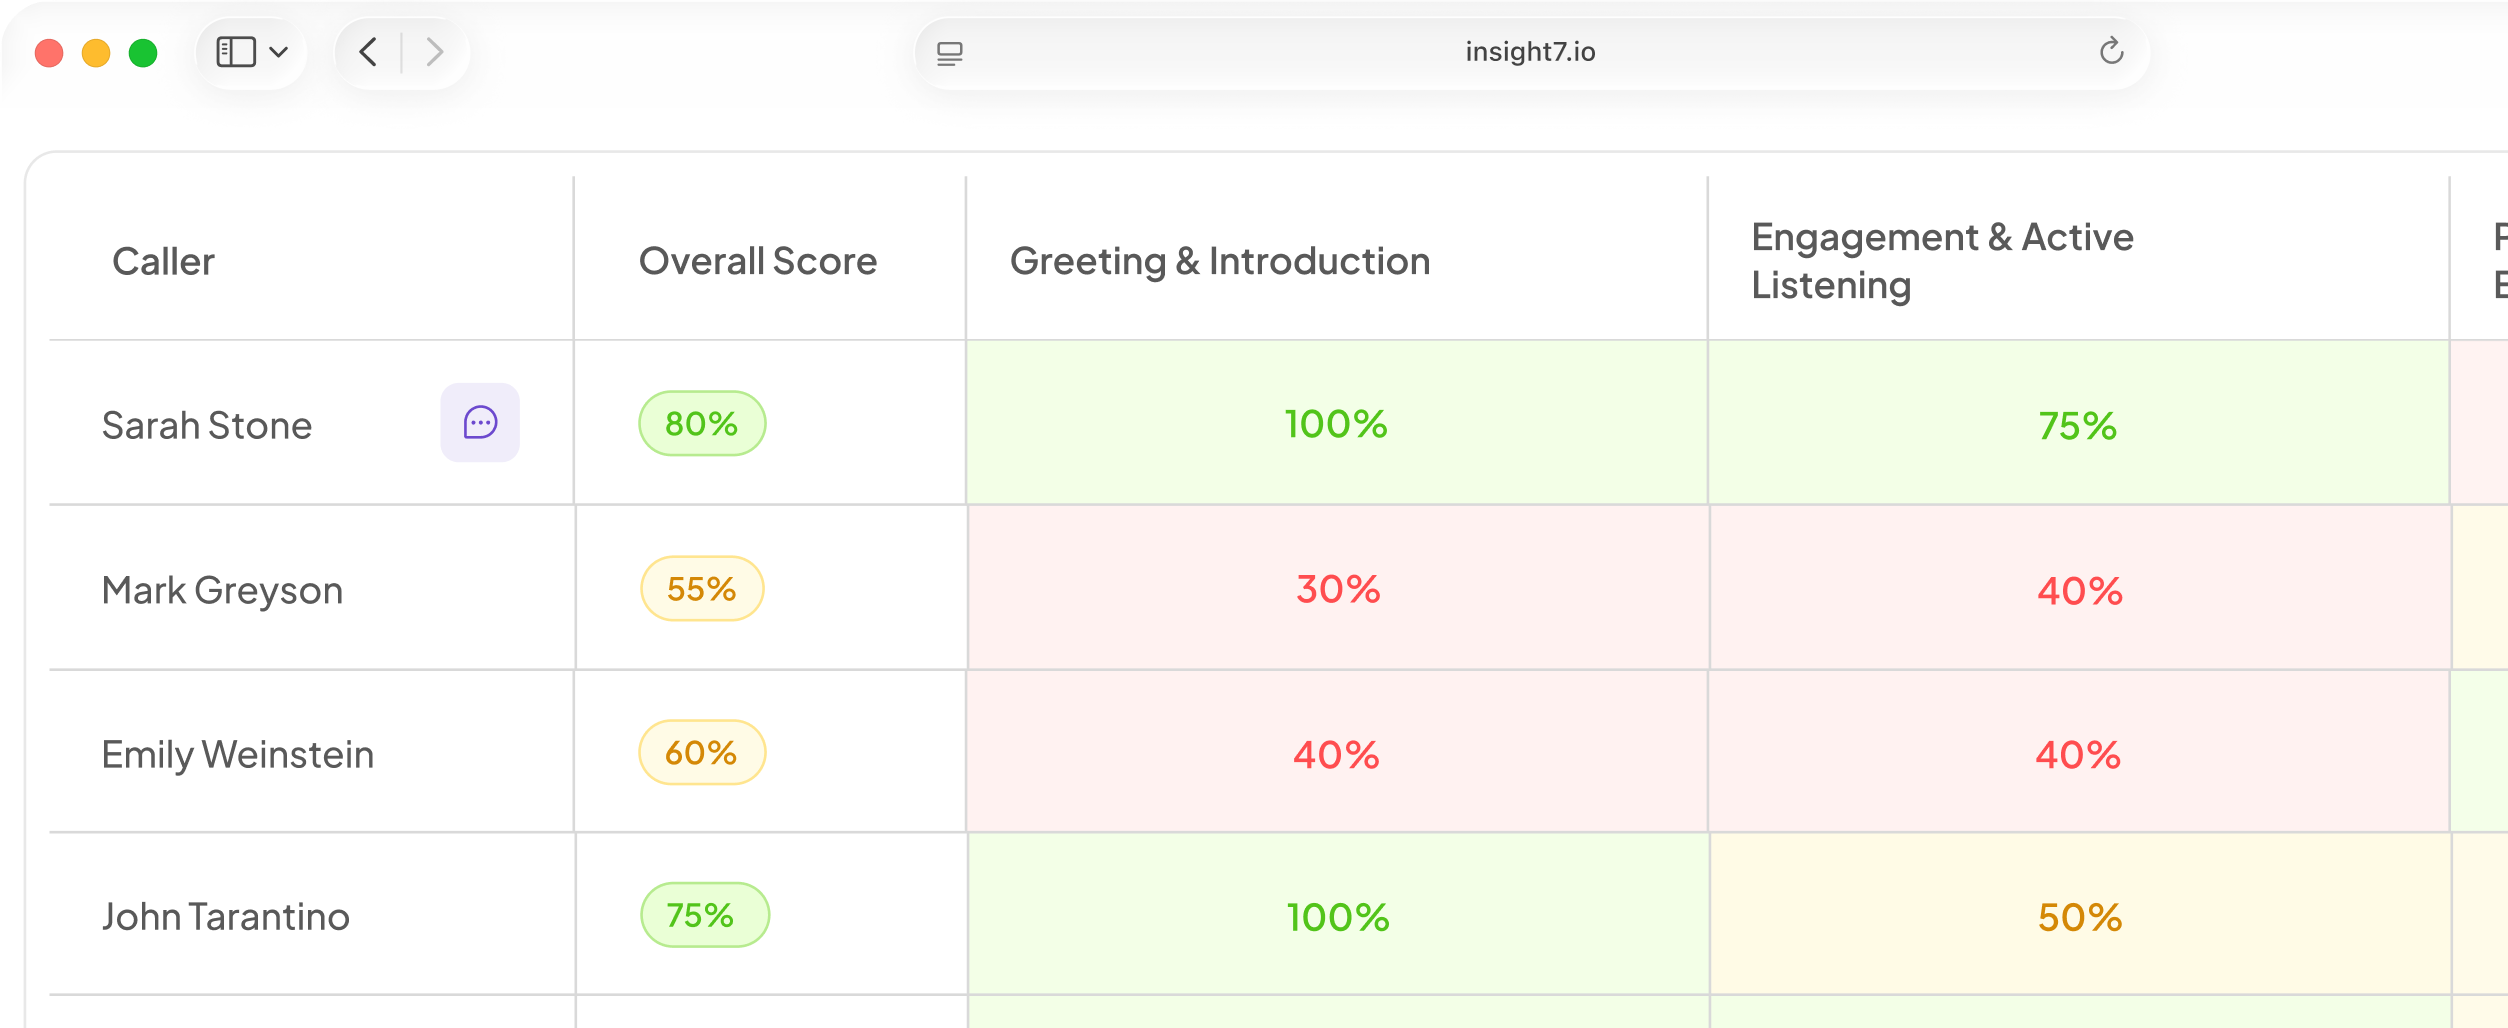
The provider's clinical lead also flagged a related problem in a separate conversation. One criterion was auto-zeroing an assessor's entire score whenever a required item was not raised at the expected point in the call, even when the patient's answer to a later question effectively covered the same ground. A zero-score rule overrides the rest of the evaluation the instant its trigger condition is not met in the expected place. If the same information surfaces later in the conversation, the system does not credit it, producing a score that does not reflect what happened on the call, and handing the assessor a legitimate reason to dispute it. The fix was not a new appeal step. It was to loosen the criterion's strictness, so the trigger only fires when the information genuinely never appears anywhere in the call.
Loosen the trigger condition before you design an appeal step for it. The fix belongs in the rubric, not in the workflow around it.
This is the failure we see most often across the operators we work with, in sectors well beyond healthcare: a single all-or-nothing rule fires on a technicality, and the appeal process built around it treats the symptom instead of the cause.
If you want to see how a change like this plays out against your own calls before you commit to it, book a demo.
Let Disputes Rewrite Your Rubric
Treat a second or third contest on the same criterion as a design signal, not a queue to clear faster.
A rubric criterion that keeps getting contested is rarely a training problem. It is evidence that the rule does not match how the call actually goes: information arrives in a different order, through a different question, or from a different person than the criterion assumes, and the score never adjusts for that. Fixing that one rule removes the dispute for every future call it would have hit, not just the one an agent happened to flag this week.
Track disputes by criterion, not by agent. The fix that removed the telehealth provider's recurring complaint came from noticing the same rule kept generating the same objection, not from reviewing assessors one at a time.
At the organization, the same pattern showed up when a scorecard was treated as fixed after launch: one rigid rule kept producing the same complaint from different agents, until the recurring complaint was traced back to that specific rubric line rather than treated as isolated feedback.
Questions People Ask Us
Should agents ever be allowed to contest a score directly?
Only if your manual process already lets them see and challenge their own paperwork without a supervisor in between. If today a supervisor signs off before an agent ever sees a number, giving the agent a self-serve contest button changes who is accountable for the score, not just how a dispute gets filed.
How fast should a disputed call be re-reviewed?
Set a turnaround before launch, not after the first dispute sits in a queue. A same-day or next-day re-listen keeps the contest tied to a coaching conversation that is still relevant. Past a week, the agent has usually moved on to arguing about a different call entirely.
What if the automated score and a human reviewer disagree?
Treat the gap as information about the rubric, not a tie-break to resolve call by call. If an expert would fail a call that scored well, the criteria are measuring the wrong thing, and no amount of case-by-case adjudication fixes that. Only a change to the criteria does.
Should every rubric item be contestable?
No. Items that record a fact, like whether an account number was captured, do not need a contest path because there is nothing to argue over. Reserve the contest workflow for items that involve judgment: tone, depth of a follow-up, whether an answer actually solved the problem.
Where To Start
If you are building this for the first time, start with the ownership question, not the interface. Sit down with whoever currently signs off on scorecards in your operation and ask them, specifically, who they would want raising a challenge on their behalf. The answer will tell you more about the workflow you need than any feature list will, and it is worth settling before a single line of the rubric changes. When you are ready to test it against your own calls, book a demo.