
TL;DR
An automated QA score and a human auditor often disagree, and usually not because the system got the call wrong. They disagree because the criteria measure whether a step happened, while the auditor is judging how well it happened afterward. A checklist can reward an assessor for asking the right question and still miss that they never followed up on what the answer revealed. Closing that gap isn't a matter of writing more rules. It means showing the system real examples of what the human calls good and bad, and rebuilding the criteria's definition of success from there. Work through this and you'll know exactly where to look first when the two scores stop matching, and how to close the gap without turning your scorecard into an ever-growing rulebook.
Run this before touching the model
Before you touch a single scoring rule, run through this sequence in order. Each step earns its place in the sections below, and skipping ahead usually means redoing the work once the real cause turns up.
| Step | What to do |
|---|---|
| 1 | Name what the human auditor is rewarding that the score isn't. Ask "did they do X" versus "did they do X well." |
| 2 | Pull a matched set of calls the auditor scored high and low, with their own notes on why. |
| 3 | Hand those labeled pairs to whoever configures the scoring criteria, instead of writing the nuance into more rules. |
| 4 | Start automated criteria on the mandatory, checkable layer only: was the topic raised, was the disclosure made. |
| 5 | Check every all-or-nothing rule for false negatives caused by information that arrived later or indirectly. |
| 6 | Build a running correlation check between the automated score and the human score, not a one-off comparison. |
| 7 | If the disagreement turns out to be outcome versus process, redefine what "success" means in the criteria before you adjust anything else. |
If you already know which step you're stuck on, jump straight to that section. The rest of this page works through each one in the order it usually surfaces.
Ask if they did it well
Name what the human auditor is rewarding that the score isn't, before you change a single weight. Most QA criteria are built to check whether a step happened: was the question asked, was the topic raised, was the disclosure made. A human auditor watching the same interaction is usually judging something one layer deeper, how well the person handled whatever came back. Those are different measurements, and a checklist can score the first one perfectly while missing the second entirely.
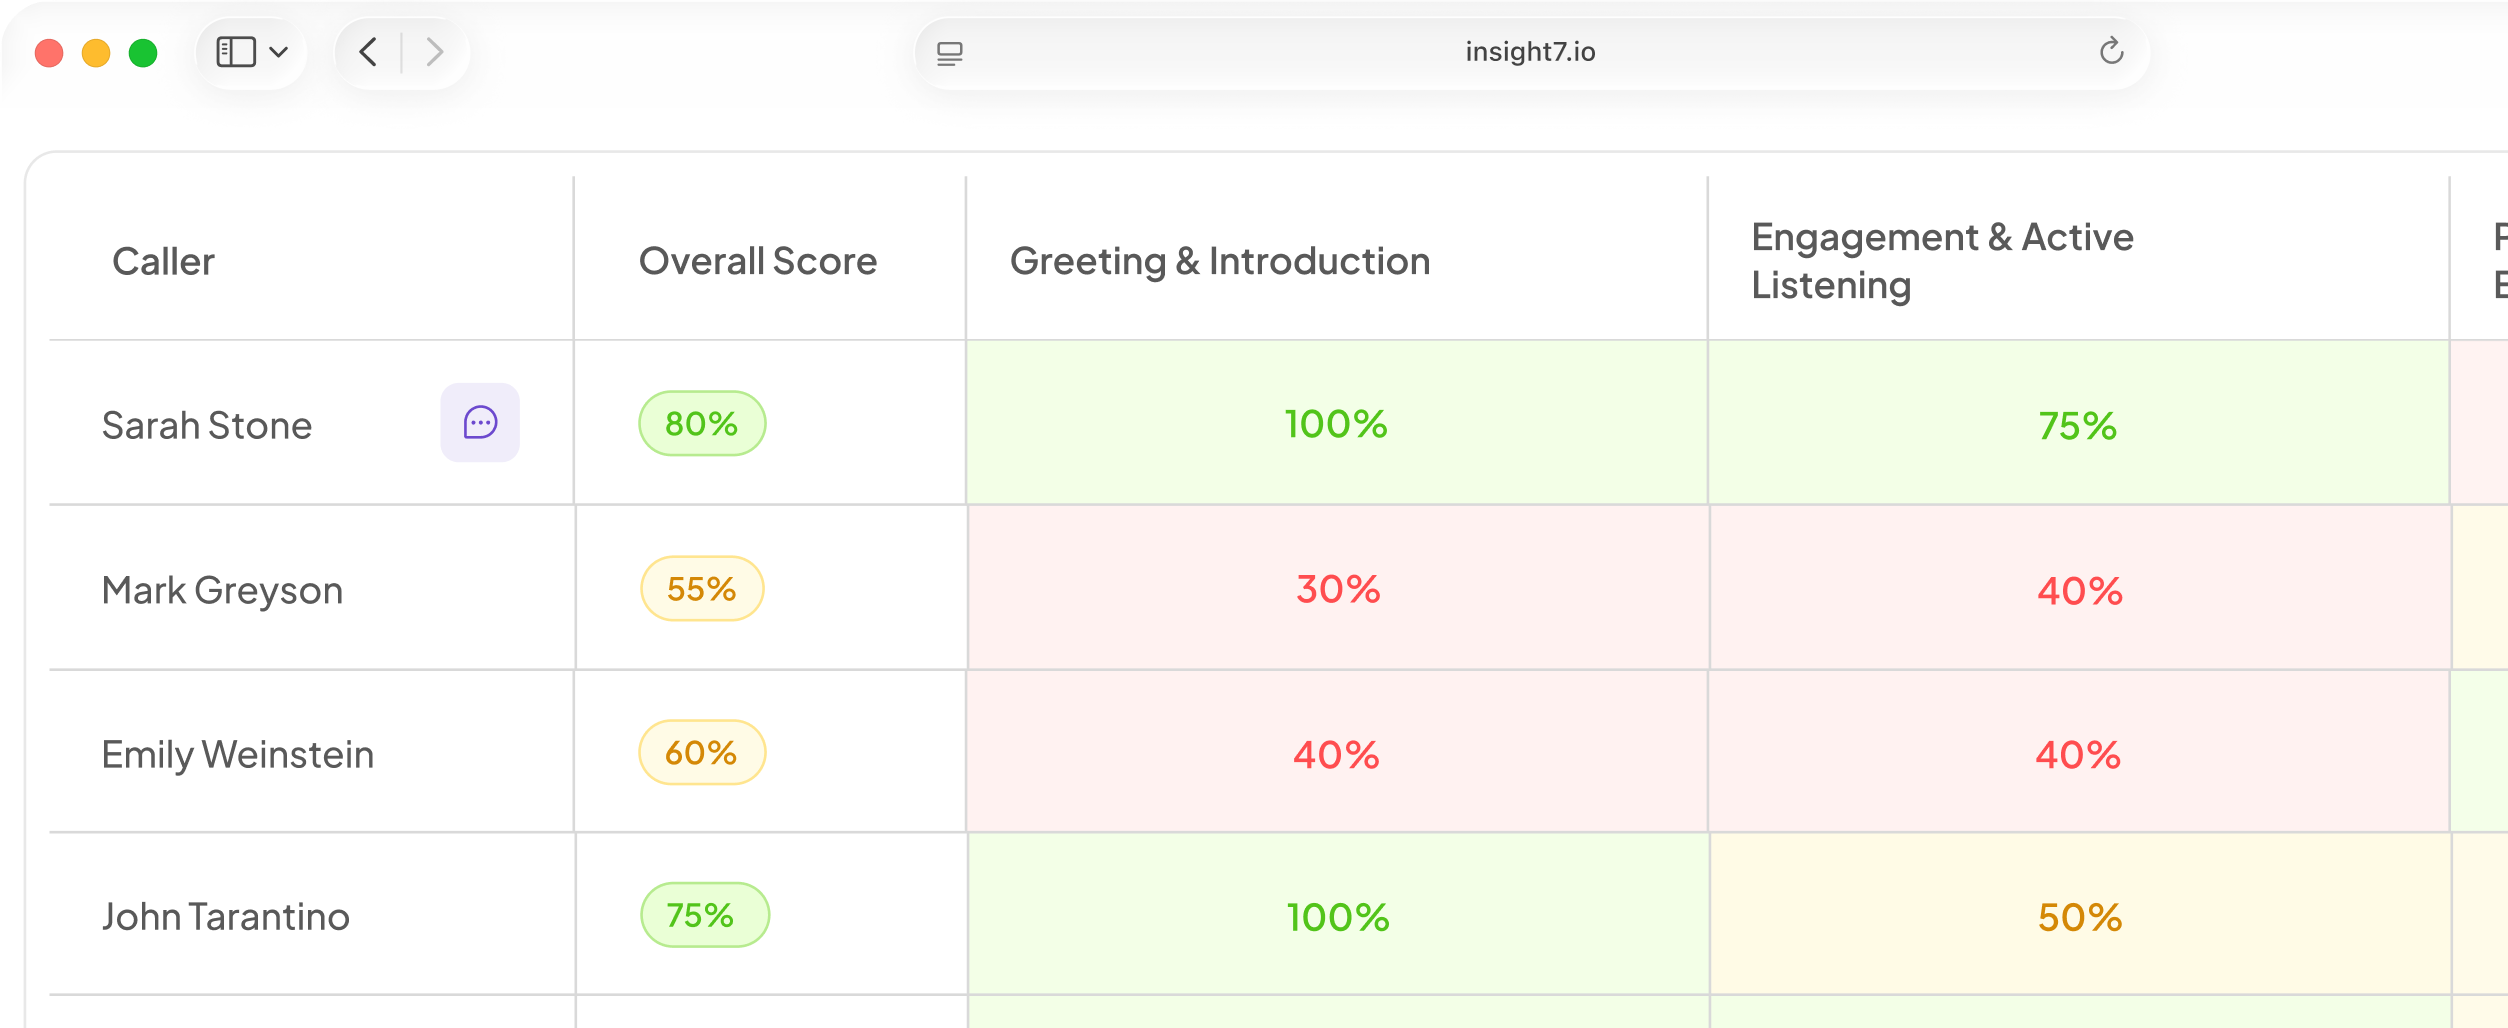
A healthcare provider running remote clinical assessments makes this concrete. Its clinical lead audits assessors by watching their session recordings and scoring them against a mix of mandatory checklist items and clinical judgment. On one assessment he had already judged poor enough to end the assessor's contract over, the automated score came out at 84 percent. The patient had disclosed something significant partway through the call, and the assessor asked the standard follow-up questions but never explored what the disclosure meant for the assessment. The automated criteria rewarded the fact that the follow-up questions got asked. The clinical lead scored the call badly because the assessor never did anything with what those questions turned up.
Before adjusting any criterion, write the one sentence the human auditor would give as the reason for their score. Then check whether any criterion in your scorecard actually measures that sentence.
A score that credits the question and ignores the answer does not just mis-measure the call. It tells the assessor that the follow-up never mattered.
Send labeled pairs, not more rules
When the criteria and the human keep disagreeing, hand over matched examples the auditor has already scored, instead of trying to write the nuance into new rules. The instinct to add a rule for every exception is where most scorecards go wrong, because judgment-heavy nuance is open-ended. There's always another wrinkle, another "well, but what if."
That provider's clinical lead took the other route. He pulled together a spreadsheet of assessments already labeled high quality and low quality, each with the detailed feedback his team had already written explaining why. Rather than trying to specify in advance what "exploring a disclosure appropriately" looks like, the goal was to let the behaviors behind a good assessment surface from examples a human had already judged: the quality of a follow-up question, not just its presence.
Pull the pairs from calls a real auditor has already scored, using their own notes as the reasoning, rather than new examples built for the exercise. Manufactured examples teach a system what you think matters. Labeled disagreements teach it what actually mattered to the person you're trying to match.
If you want to see how labeled pairs like these get built into a live scorecard, you can book a walkthrough at https://insight7.io/book-demo/.
Start on the checkable layer only
Build the first version of any scorecard on the layer that's actually checkable, and add judgment-heavy criteria later, one at a time. Save things like the quality of a follow-up or the warmth of an explanation for a second pass, once the checkable layer is proven out.
The reason is practical. A checkable item has one clear right answer that a system and a human will agree on nearly every time. A judgment item has many acceptable versions of "good," and no two auditors describe it the same way. Mixing the two in a first release means every disagreement gets blamed on the system, when half of them are really disagreements about wording a human auditor never had to make explicit before.
If a criterion needs a sentence of explanation to describe what "good" looks like, it isn't ready for the first pass. Ship the ones that don't need explaining, confirm they agree with your auditors, then add the harder ones back one at a time so you can tell which one caused the next disagreement.
Test zero-rules for false negatives
Check every all-or-nothing criterion for cases where the missing information actually showed up later in the conversation, just not where the rule expected it. Those aren't misses. They're false negatives, and a scorecard full of them will always look harsher than the human auditor watching the same calls.
The same clinical lead ran into this on an earlier call. One of the provider's criteria scored an assessment at zero the moment a required topic wasn't mentioned at its expected point, even when the patient's own answer, given elsewhere in the conversation, effectively covered it. He flagged the rule as "too harsh" relative to how he'd score the same assessment himself: the substance had been covered, just not on cue.
A rule that only credits information at the expected moment scores the shape of the conversation, not its substance.
Test every zero-if-absent rule against a handful of calls where the topic came up out of order, before you trust the score it produces.
Track agreement on a running basis
Compare the automated score against human judgment on a running basis, not as a one-off calibration you trust forever. Both sides drift. Criteria get retuned, assessors change how they work, and a gap that closed in month one can reopen by month three without anyone noticing, until an auditor happens to rewatch a call the system scored well.
That provider now builds a chart every month specifically to check whether its automated scores are still tracking what its own team sees when they review the same assessments. It isn't treated as a special project. It's a task done between other priorities, on a fixed cadence, precisely because a single side-by-side comparison only proves agreement on the day you ran it.
Set a recurring, calendared check, weekly or monthly, rather than confirming agreement once and moving on. The moment you stop checking is usually the moment the gap starts growing again.
Redefine success before you tune
If the disagreement is really about outcome versus process, redefine what the criteria call success before you adjust anything else. When a scorecard measures adherence to a set of steps while the business actually judges calls by outcome, no amount of rule-tuning closes the gap, because you're tuning the wrong target.
A self-storage facility operator ran into this directly. Its managers watched scores land between 55 and 65 percent week after week and read them as failing grades, even though John and Melissa felt the scores did not accurately reflect how their stores were actually performing. The criteria had been built around following a defined set of steps in the call. What the managers actually cared about was whether the call ended in a booked appointment or a closed sale. The team shifted the grading emphasis from strict adherence toward call success, and once the criteria matched what the business actually rewarded, the median score moved from around 50 percent into the 70s. The operator then set an automated alert at the 50 percent mark, for calls that still needed coaching attention, against that new baseline.
The problem was never the scoring. It was that the criteria had never been told what a good call actually produces.
Before you touch a threshold or a weight, ask whether the disagreement in front of you is about how a step was done, or about whether the criteria are chasing the outcome the business actually wants.
Questions about scoring agreement
How much disagreement between the automated score and a human auditor is normal?
Some gap is expected on any call with a judgment component, and a single disagreement on a single call doesn't mean the criteria are broken. Treat it as a signal worth investigating once the same criterion produces a gap on several calls in a row, not after the first one.
Should I wait until the checkable layer is fully agreeing before adding judgment criteria?
Not necessarily. You can start identifying the underlying judgment-based behaviors in parallel with fixing the checkable layer, as long as you're working from real labeled examples rather than guesswork. Feed the system matched examples of calls your auditors have already scored high and low, together, so it can learn the underlying behaviors rather than only tuning the checkable layer in isolation first.
What if my human auditors don't agree with each other?
Then no automated criteria can be tuned to match "the" human score, because there isn't one. Calibrate your auditors against each other first, using the same labeled-pairs approach, before using their scores as the target for the automated system.
How many labeled examples do I need to send before the criteria improve?
There's no fixed number, but a handful of clearly good and clearly bad calls from a single assessor teaches the system less than a smaller set spread across several assessors and several situations. Breadth of behavior matters more than volume of examples.
Where to start this week
Pick one call this week where your automated score and your best auditor genuinely disagreed, and work that single disagreement all the way through the sequence above before you touch anything else on the scorecard. The gap rarely comes from one hidden flaw in a model. It comes from a definition of success that was written down once and never checked against what your auditors actually reward. If you want help building that check into your own scoring setup, book a walkthrough at https://insight7.io/book-demo/.