
TL;DR
A collections call and a sales call can sit in the same queue and still be graded on entirely different jobs, but a shared scorecard rarely knows that. If you run QA across several call types or teams, the fix is not a vaguely "more accurate" rubric. It is deciding, axis by axis, where a shared scorecard actually breaks down: which call types need their own outcome, which items should zero out a score instead of just lowering it, whether your scales line up with each other, and whether your pass threshold still matches how your team scores today. Skip that axis-by-axis work and you end up rewriting rubrics forever without ever finishing. Get the five decisions right once, and every score in your program finally measures the job the call was actually for.
Your Rubric Customization Audit Table
Copy this table and fill in one row for every call type or team your program covers. Every cell is your own answer, not ours, and a blank cell tells you exactly where to start.
| Call type or team | Primary business outcome | Critical-fail item(s), if any | Scoring scale used, and whether it matches other layers tracked | Date threshold last checked against current score distribution |
|---|---|---|---|---|
Each column follows from a section below. The outcome column is explained under "Score the outcome, rank the priority." The critical-fail column is explained under "Make critical items zero, not heavy." The scale column is explained under "Match scales, write KPIs into rubrics." The threshold column is explained under "Recalibrate thresholds as scores drift." A row you cannot fill in confidently is the row that needs work first.
Name The Axis Before You Customize
Customize on a specific axis, never on a vague request to make the rubric more accurate. When a manager asks for a rubric to be "better," that request has no shape, and whoever builds it ends up guessing at what to change. There are five main things a QA rubric is customized on most often: the outcome it scores, the framework it uses, whether an item can zero out the score, the scale it reports on, and the threshold that turns a score into an action. Most real customization requests map to one of those five (criteria weighting is a common exception), and naming which one before you touch the rubric is what turns a vague complaint into a specific fix.
If you can't say which of the five axes you're changing, you're not customizing, you're guessing.
Score The Outcome, Rank The Priority
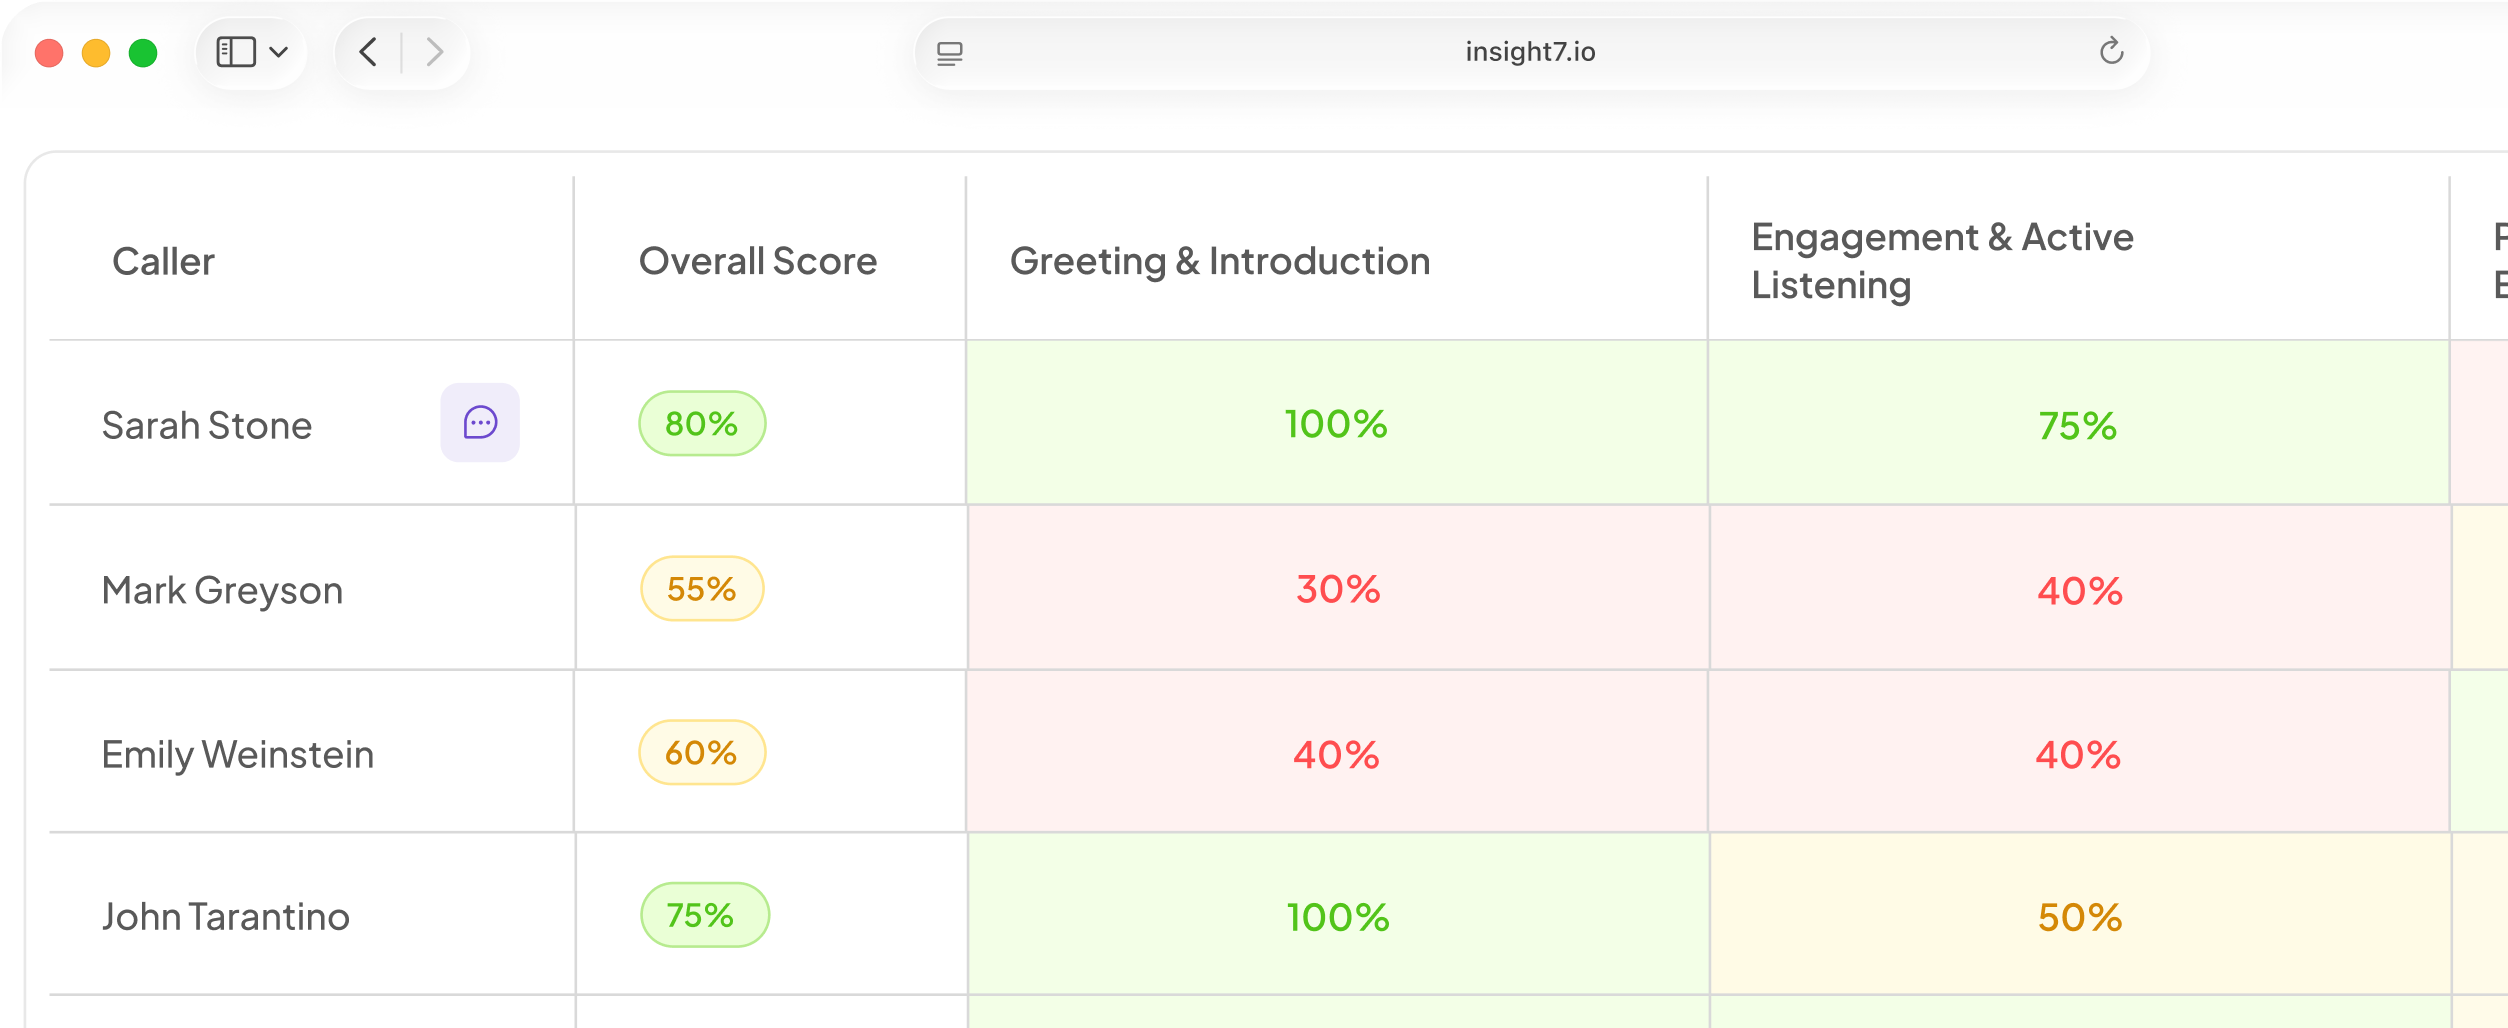
Judge each call type by the business outcome it exists to serve, not by a generic checklist that happens to already be sitting in your platform. A self-storage facility operator running multiple locations with property managers and sales agents learned this the hard way. Every call type at that operator, including collection calls, follow-up calls, and sales calls, was being scored against one inbound-lead rubric that had simply been carried over by default. Scores landed at 55% to 65%, and store leadership treated those numbers as failing grades, even though the stores themselves were performing fine. The rubric was measuring adherence to a checklist built for a different job.
The same operator's sales leadership then ran into a second version of the same problem. They wanted a rubric that could shift week to week between closing deals and gathering information, but the evaluation system could only apply one rubric per call. Rather than force a generic criteria set to cover both, the team ranked the priorities and defined a single focus for that call type: asking the right questions, setting appointments, and closing deals. That ranking, not a cleverer rubric, is the change the team made to close the gap.
Write the outcome down in one sentence before you write a single criterion. A rubric built for one call type does not just mis-score another. It tells leadership their operation is failing when the calls themselves are fine.
Split Where The Operation Already Splits
Split rubrics along lines your operation has already drawn, not along new categories invented for the scorecard. An insurance provider operating a large multi-channel contact center for policy servicing, claims, and complaints had already done this work long before any scoring platform entered the picture. Its manual QA process ran a different SOP and grading approach for phone calls, email, WhatsApp, and walk-in interactions, because each channel carries different evidence of what actually happened and different expectations for what an agent has to capture. The channel split was an operational necessity first, and the rubric only needed to catch up to it.
A waste management company operating customer service call centers for waste collection and disposal accounts drew the same kind of line between teams rather than channels. Its leadership decided that sales calls needed a completely different framework, built around a qualification-based sales methodology, from the empathy, resolution, and tool-navigation framework used for support calls. The team decided a single shared criteria set could not serve both, so each call type got its own framework instead.
If your SOP already treats two call types differently, your scorecard should already agree with it.
Fewer Categories Beat Many Narrow Ones
Group criteria into a small number of well-defined categories instead of writing a new rubric for every scenario you can imagine. That same waste management company originally proposed a training curriculum built from dozens of narrow, scenario-specific rubrics. After review, the team scrapped that plan in favor of broader category-level sessions, such as call opening and empathy and active listening, each opening with an explicit statement of what was expected before the representative even began practicing. Fewer categories did not mean less rigor. It meant a manager could actually assign the right session without hunting through a spreadsheet first.
A rubric only works if a manager can assign it without hesitating and a rep can recall it without checking. Add enough scenarios and it stops being a scorecard and turns into an archive nobody opens.
If a manager has to search for which sheet applies, the rubric has already failed its first job.
Make Critical Items Zero, Not Heavy
Layer a critical-fail rule on top of your weighted criteria for anything that is a compliance failure rather than a quality deduction. Weighting alone cannot express that kind of failure, because a heavily weighted item can still be outweighed by everything else the agent did well. The insurance provider described above ran into this directly. In its existing manual grading sheet, missing a customer's policy number was not treated as a point deduction. It was treated as an automatic zero for the entire evaluation, regardless of anything else the agent did correctly, because in a regulated industry a missed policy number is not a quality gap, it is a compliance failure. Building that same behavior into an automated rubric requires a separate rule layered on top of the weighted criteria, one that says explicitly: if this specific outcome is not met, the entire evaluation scores zero. Treating it as just another heavily weighted item, however high the weight, will still let a strong call absorb the miss.
Ask of every criterion: if this is missed, should the score drop, or should it end? Only weight the first kind.
If you want to see how a critical-fail rule sits alongside weighted criteria on a real scorecard, book a demo.
Match Scales, Write KPIs Into Rubrics
Match any new scoring layer to the scale your team already trusts, and write your operational KPIs directly into the rubric instead of tracking them alongside it. The waste management company ran into the first half of that problem when a new skills-tracking view, built on a ten-point scale, sat right next to its existing live-call scoring on a percentage scale. A representative's overall call score sat at roughly 60% to 75%, while the same person's skill score showed up as something like 5.0 to 5.8, with no stated relationship between the two numbers. Because the scales didn't line up, the team couldn't easily map the new skill score to the score they already trusted, feedback Insight7 planned to address before the feature fully shipped.
The same company ran into the second half of the problem from the other direction. Leadership set a new operational KPI, a three-minute target for call handling time, and asked for that target to be built directly into how the AI rated performance rather than tracked as a separate number leadership watched on the side. An operational KPI does not show up in a quality score just because leadership cares about it. It has to be written into the criteria as something the rubric checks directly, or the scoring and the business's real priorities keep drifting apart.
Nobody can act on a mystery number. A skill score with no stated relationship to the percentage sitting next to it gets ignored, however good the coaching insight buried inside it might be.
A KPI leadership cares about only shows up in the score if a criterion checks it directly.
Recalibrate Thresholds As Scores Drift
Recheck your pass and alert thresholds whenever the score distribution shifts, not only when you touch the rubric itself. The self-storage operator's stores set up automated alerts for any call scoring below 50%, a number that had made sense when the program started. By the time the alert was actually configured, the median score across the program had already moved from roughly 50% into the 70s. The 50% threshold was still technically correct, but it no longer meant what it used to mean, and the team had to stop and work out where the new alert line should actually sit.
A threshold set against last year's scores is measuring last year's program.
Customization Ends At Five Axes
Treat outcome, framework, critical-fail, scale, and threshold as the complete list of axes, not as a template for open-ended tweaking. Once a call type has an answer for all five, the right move is to stop customizing that rubric and start comparing its results against the other call types in your program. This is also the failure we see most often once teams get comfortable with customization: they keep adding nuance to a rubric that hasn't earned it yet, usually by trying to score judgment calls before the basic mandatory checks are even reliable. Get the five axes right first. Nuance is worth adding later, not instead.
More rubrics are not more rigor. A finished audit table is the sign you are done, not the sign to keep splitting.
Questions About Customizing QA Rubrics
How many QA rubrics does one program actually need? Most programs that customize well land somewhere between three and six rubrics tied to genuinely distinct outcomes or frameworks. If your count keeps climbing past that, the usual cause is that call types are being defined by topic or scenario instead of by the outcome they serve.
Should new agents be scored on a different rubric than tenured agents? Seniority is not one of the five axes, and giving new agents a separate rubric usually backfires because their scores stop being comparable to anyone else's once they graduate from onboarding. Handle the difference through training assignments and coaching cadence, and keep the outcome rubric identical from day one.
What is the real difference between a critical-fail item and a heavily weighted one? A heavily weighted item still lets a strong call absorb one bad answer elsewhere in the score. A critical-fail item should zero the entire evaluation regardless of what else went well, and it should also route an alert to a supervisor immediately rather than waiting for a weekly report. Reserve it for compliance and safety, not for anything a coach would simply flag for improvement next time.
How often should a pass or alert threshold be recalibrated? Recheck it every time you change the rubric, and at minimum once a quarter even if you haven't touched it. If the median score has moved by more than a few points since the threshold was set, the threshold is measuring the old program, not the current one.
Can a single call be scored against two rubrics at once? Most evaluation platforms score a call once, against one rubric, so if two priorities genuinely matter, rank them and build the rubric around the one that wins. If you truly need both views side by side, run the same calls through two separate evaluation projects with two different criteria sets rather than expecting one merged score to hold both.
Start With One Rubric Change
Do not rebuild every rubric in your program at once. Start with whichever call type produces the biggest gap between its score and what your best manager would say about the same call, because that gap almost always points straight at the axis that is most broken, and fixing one axis well teaches you more about the other four than any amount of upfront planning will. If you want help finding that gap and building the rubric around it, book a demo.